
by SQLStack
Exact types. Loud failures. Bounded memory.
Website ·
Docs ·
Quickstart ·
Benchmarks ·
Discord
SQLLoad loads databases, files, APIs and Kafka into your warehouse. sqlload plan shows every
table and how it loads before anything moves, and plan -v adds each new table's column types and
the run's memory budget. Decimals keep their precision, a value a column can't hold exactly fails
its table, naming the column and the value, and each run has one memory budget. Tables with a
cursor column carry on from the warehouse's own maximum, so there's no state to drift.
pip install sqlload # or: uv tool install sqlload
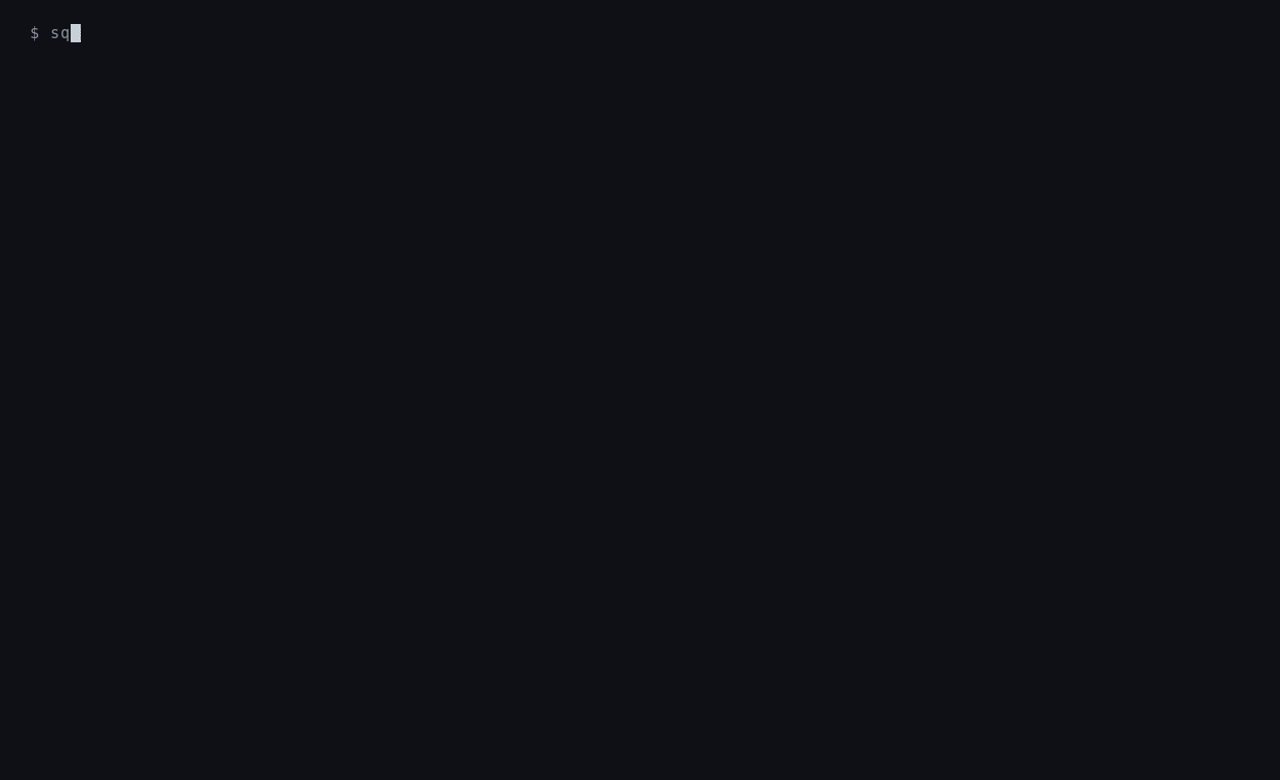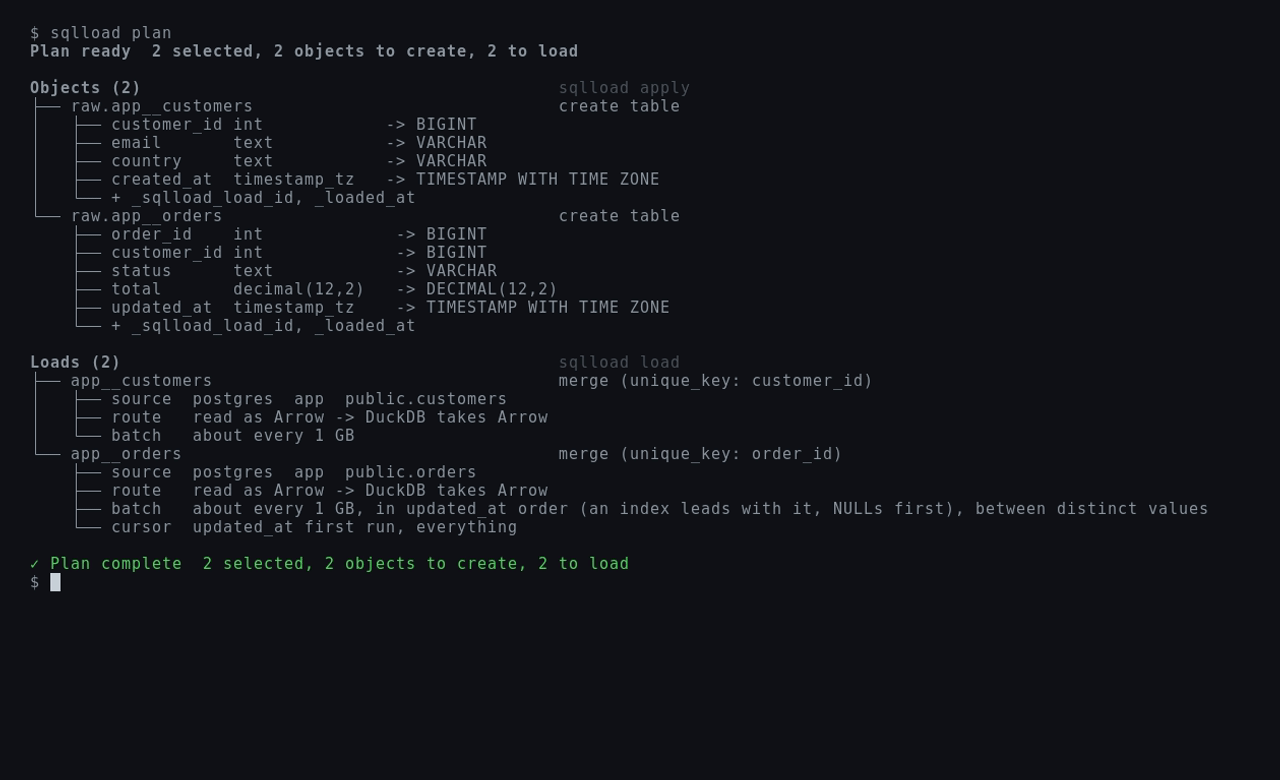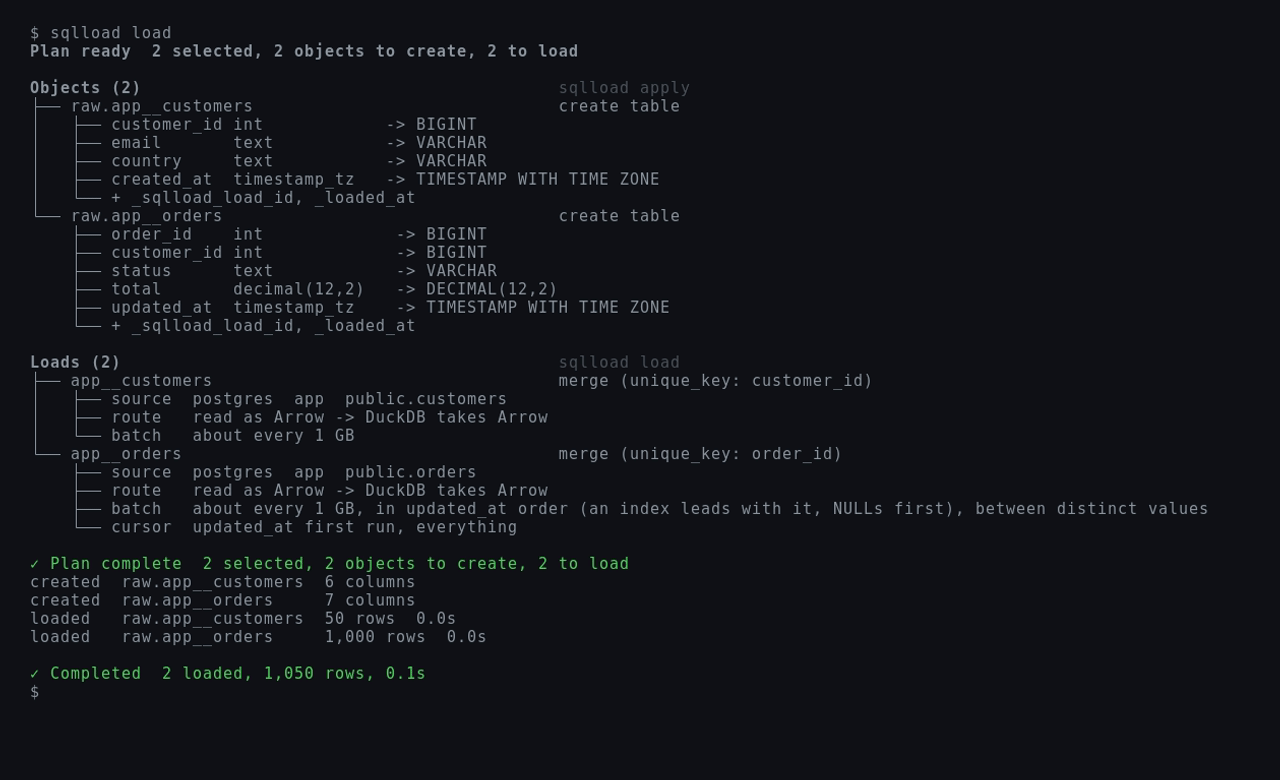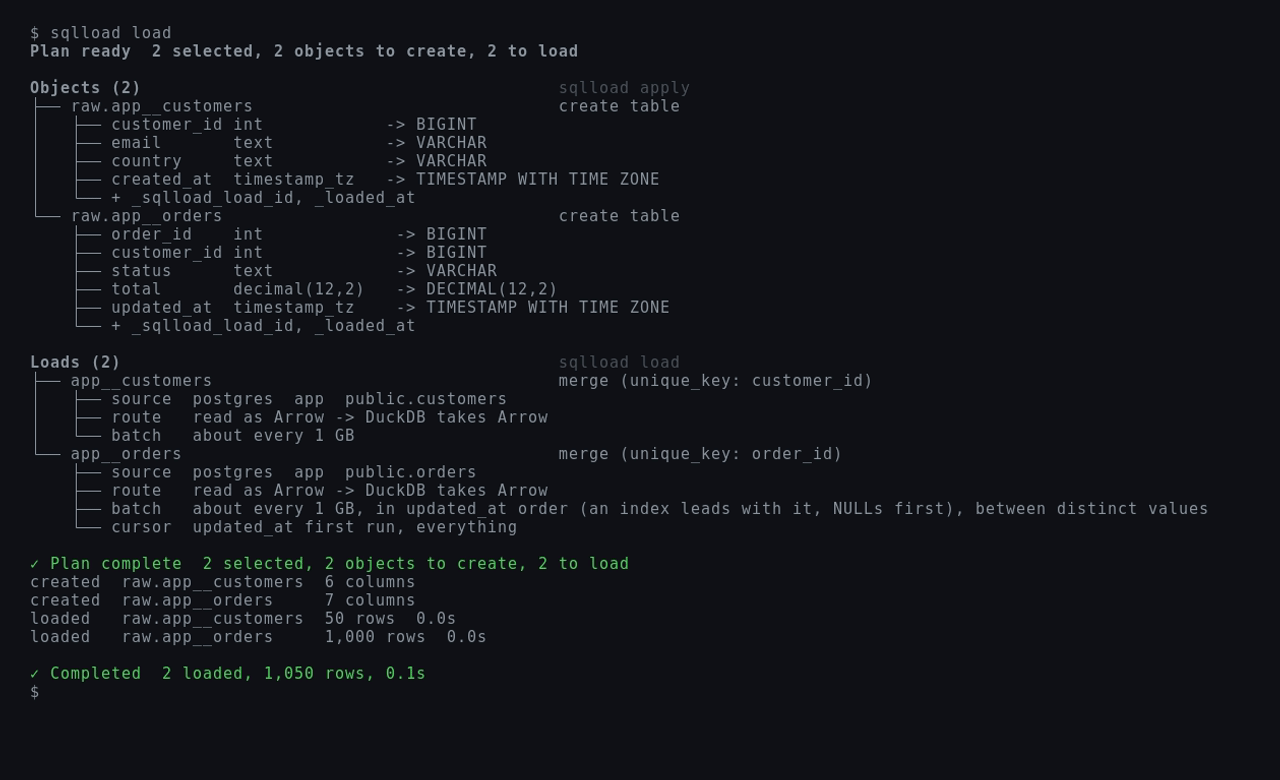
In the playground project, sqlload plan shows the
tables it will create and how each loads, and sqlload load creates and fills them. With
cursor_column misspelled, the next load refuses the orders table before touching it, and says
which column was meant.
sqlload plan     # every table and how it loads, before anything is created (-v: column types)
sqlload apply    # create the tables
sqlload load     # load them
A sqlload.toml names your sources and targets. sqlload playground writes one that loads
sample CSV files into DuckDB, with no database or credentials; the
quickstart runs it. To load one table once with no
configuration file:
sqlload copy orders/ duckdb://shop.duckdb#raw.ordersMoving from dlt? Coming from dlt maps sources,
write dispositions, incremental loading, rest_api and filesystem, and keeps the table and column
names dlt gave your tables.
- Exact types. A source's
decimal(12,2)loads asDECIMAL(12,2)(NUMBER(12,2)on Snowflake), timestamps keep their microseconds, and a pinned type narrower than the live column failsplanrather than cutting values. See contracts. - Loud failures.
plannames each problem it can find, such as a misspelled column, a narrowing type or a budget too small, and its fix, before anything is created. A commit whose checks fail publishes none of its rows, every commit lands whole even if a load is killed halfway, and in a warehouse (except a ClickHouseOrdinarydatabase) a full refresh swaps in at once, so readers see the old table or the new one, never a mix. - Bounded memory. A run has one memory budget, shared out between its tables. A budget too small for even one table is refused before anything loads, and near the limit SQLLoad stops a table, or the run, and rolls back what it was writing, rather than waiting for the operating system to kill it.
- No hidden state. Tables with a
cursor_columncarry on from the warehouse's own maximum of the cursor column, so a table you fix or reload by hand never disagrees with a state file.
Faster, in a fraction of the memory. The same data loaded by each tool on one 4-vCPU, 8 GB machine; lower is better:
| Scenario | SQLLoad | ingestr | dlt |
|---|---|---|---|
| Parquet in S3 into Snowflake, 100M rows: wall time | 134.4 s | 182.3 s | not run |
| The same runs: peak memory | 54 MiB | 3,836 MiB + 5.7 GiB temp disk | not run |
| Postgres into Snowflake, 1M rows: wall time | 14.56 s | 16.38 s | 29.36 s |
Parquet in S3 into Snowflake: wall time and peak memory from the same 100M-row runs, median of 3, 18 November 2026, sqlload 0.70.1 and ingestr 1.1.82. On SQLLoad's default route Snowflake copies the files itself, so no row passes through SQLLoad and it uses no disk; ingestr streams every row through its own process and spilled 5.7 GiB to disk. Postgres into Snowflake: median of 5 runs, 6 November 2026, sqlload 0.11.1, ingestr 1.1.82, dlt 1.32.0 (its connectorx backend for Postgres); peak memory 131 MiB for SQLLoad, 495 MiB for ingestr and 341 MiB for dlt.
See the benchmarks for every scenario, the method, the versions and how to run them yourself.
| System | Source | Target |
|---|---|---|
| Postgres | ✓ (incl. CDC) | ✓ |
| Snowflake | ✓ | ✓ |
| BigQuery (beta) | ✓ | ✓ |
| Databricks (beta) | ✓ | ✓ |
| ClickHouse | ✓ | |
| DuckDB | ✓ | ✓ |
| MotherDuck (beta) | ✓ | ✓ |
| ODBC | ✓ SQL Server, MySQL, OpenEdge | |
| Files | ✓ Parquet, CSV, JSON, Excel, XML | ✓ Parquet, CSV |
| Google Sheets | ✓ | |
| APIs, Python | ✓ | |
| Kafka | ✓ to Snowflake, Databricks, BigQuery |
See Supported systems for every combination and write strategy.
Built in Rust. Free and open source. Apache 2.0. Contributing · Changelog · Discord
Part of SQLStack.